Arabic Knowledge Is Hard to Find. AI Can Fix That, If Libraries Get Their Data Ready

Newsroom  /  Articles

Articles

Arabic Knowledge Is Hard to Find. AI Can Fix That, If Libraries Get Their Data Ready

Arabic is the first language of more than 450 million people but the content language of about 0.5% of top websites. How Gulf libraries can use semantic search and AI to make their collections findable.

By KGG Communications · 4 min read

Arabic Knowledge Is Hard to Find. AI Can Fix That, If Libraries Get Their Data Ready

More than 450 million people speak Arabic as a first language. Yet Arabic is the content language of only about 0.5% of the world’s top ten million websites, against roughly 49% for English. The gap is not only a matter of how much Arabic knowledge exists. It is a matter of how much of it can be found, and the answer increasingly depends on whether artificial intelligence can read it.

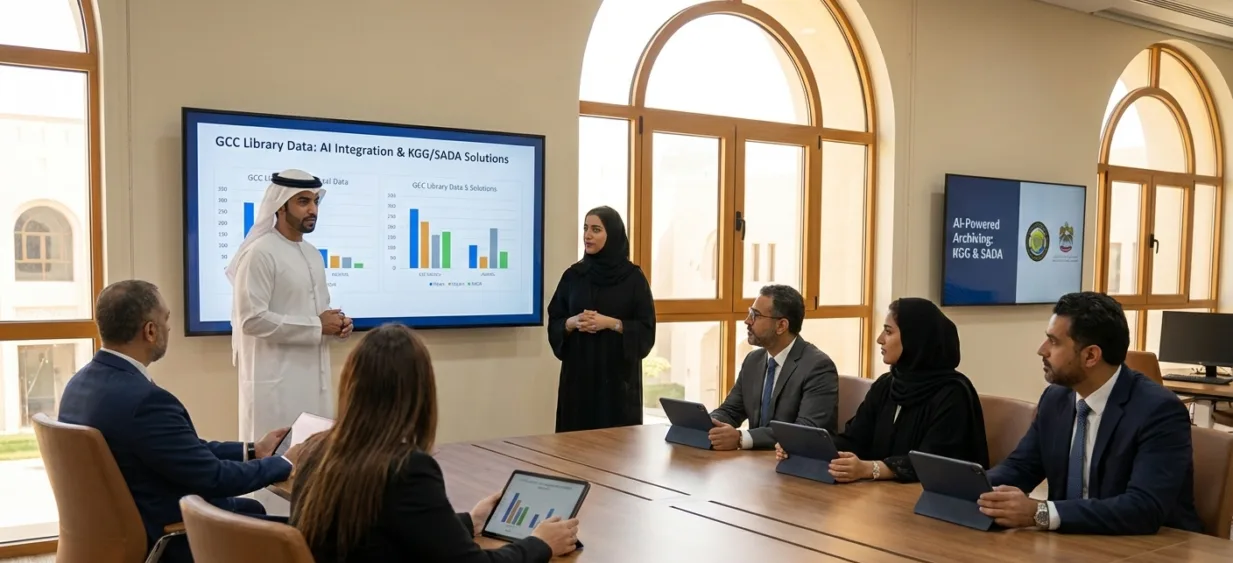
That puts the Gulf’s libraries in an unexpectedly strategic position. Their collections hold exactly the Arabic scholarship, heritage and institutional memory that the open web lacks. As students and researchers shift from typing keywords to asking questions of AI assistants, the collections that are ready for machine retrieval will be read. Those that are not risk becoming invisible.

Billions spent on reading

The region has invested heavily in the physical and digital infrastructure of knowledge. Dubai’s Mohammed Bin Rashid Library, which opened in June 2022 at a cost of about AED 1 billion, holds some 4.5 million items, including 2 million digital books and 1 million audiobooks. Universities across the Gulf have digitised theses, archives and special collections. National AI strategies, led by the UAE’s National Strategy for Artificial Intelligence 2031, now expect those assets to feed research and an economy built on knowledge.

Digitising a collection, however, is not the same as making it findable. A scanned manuscript with thin metadata is, for most users, invisible. And the tools most people now reach for first, general-purpose AI chatbots, know very little about what sits inside a university’s Arabic thesis repository.

Why Arabic defeats the search box

Traditional library catalogues match the words a user types against the words in a record. That works tolerably in English. In Arabic it breaks down for structural reasons. The language builds words from roots and patterns and attaches prepositions, conjunctions and pronouns to them, so a single written word can hold several units of meaning and an exact-match search for its root will miss it. Short vowels are usually omitted, so one written form can carry meanings that only context resolves. Modern Standard Arabic, classical texts, Gulf dialects and competing transliterations of the same name, such as Mohammed, Muhammad and Mohamed, all describe the same things differently.

Gulf collections add a further layer. An Arabic thesis may cite English sources, and an English report may quote Arabic policy. Search that treats the two languages separately returns half the picture. Reference librarians know the result well: users who conclude that material does not exist when it simply was not found.

What AI can and cannot fix

Three techniques now make a real difference. Semantic search represents meaning rather than spelling, so a query in English about water scarcity in the Gulf can surface an Arabic study on the same subject without a shared keyword. Hybrid retrieval combines that meaning-based matching with traditional keyword and metadata filters, which keeps precision high for names, dates and call numbers. Retrieval-augmented generation lets a conversational assistant answer questions only from a library’s own holdings and cite the exact sources, which is essential for academic trust.

What AI does not do is repair poor data. MIT researchers studying enterprise AI in 2025 found that about 95% of generative AI pilots produced little measurable return and traced the failures to integration and data rather than to the quality of the models. Libraries are no exception. Errors in the optical character recognition of scanned Arabic, missing subject headings and inconsistent name records will surface in every answer an AI system gives.

A sequence, not a switch

Institutions that have made progress tend to follow the same order. They begin by choosing the collection where poor findability costs users most, often theses, local heritage material or government publications, and by measuring today’s baseline: failed searches, time to find a source and the load on the reference desk. They then invest in the data itself, improving Arabic text recognition, normalising names and transliterations and enriching metadata, with specialists validating machine suggestions so the work can scale. Only then do they launch bilingual hybrid search on that collection, compare the results against the baseline and let librarians tune relevance before a wider release. Conversational access comes last, through an assistant that answers only from the collection, always shows its sources, respects access rights and protects personal data under the UAE’s Personal Data Protection Law.

Governance runs through every stage. For public and academic institutions, where data is hosted and who can see it are not technical details. Collections that include unpublished research, student records or sensitive heritage material need clear hosting decisions, role-based access and audit trails from the start. Librarians remain the curators: AI can propose subject headings, links and summaries, but people decide what enters the catalogue.

The measures of success are practical. They include the share of searches that return a relevant result on the first page, the time a researcher spends finding a source, the volume of Arabic material that becomes newly discoverable and the hours librarians recover from manual tagging. Institutions that track these from the first day can show value within a single academic term.

Where KGG fits

Kanan General Group works on the problem with its exclusive GCC partner, SADA Intelligent Solutions, whose engineers have built an AI query builder for the digital library of a major US publisher and a data annotation validation workflow that cut review cycles for a global economic organisation from weeks to hours, according to SADA’s case studies. KGG is also developing Arabic-first retrieval for library and research institutions in the region and is inviting university, public and heritage libraries to take part in early pilots.

Libraries that want to explore a pilot can talk to the KGG team about their collections.

Media enquiries and partnership requests

Contact Us

More news

All news
Articles

Riyadh Signs Health Deals by the Billion This Week. KGG Is Betting on the Clinics That Still Buy One Device at a Time

The Global Health Exhibition opens Monday in Riyadh with 2,200 brands, 500 speakers and the memory of US$35.5 billion in deals last year. KGG, which supplies medical devices and the Envision cloud radiology platform across the GCC, brings one argument to the week: the next phase of Saudi health spending will be won in the kingdom's 3,607 private medical complexes, not in the deal hub.
10 min read

Quick request

en_USEnglish